I remember the first time someone asked me to explain residuals, and I froze. The textbooks made it sound complicated, but here’s the truth: a residual is just the gap between what your model predicted and what actually happened. Once you see it that way, the rest falls into place.
In this guide, I’ll walk you through what residuals are, the residual formula, how to calculate them by hand, and how to read a residual plot. I’ll also cover the differences between residuals and errors, plus what “residuals” means in other contexts (yes, including entertainment). By the end, you’ll have a working understanding without needing a statistics PhD.
Whether you’re a student working through your first regression assignment, an analyst trying to debug a model, or someone who just stumbled on the term and wants to understand it, this guide is for you. We’ll keep the math minimal and the intuition front and center.
Let’s start with the simplest possible explanation.
Table of Contents
What Are Residuals? A Simple Explanation
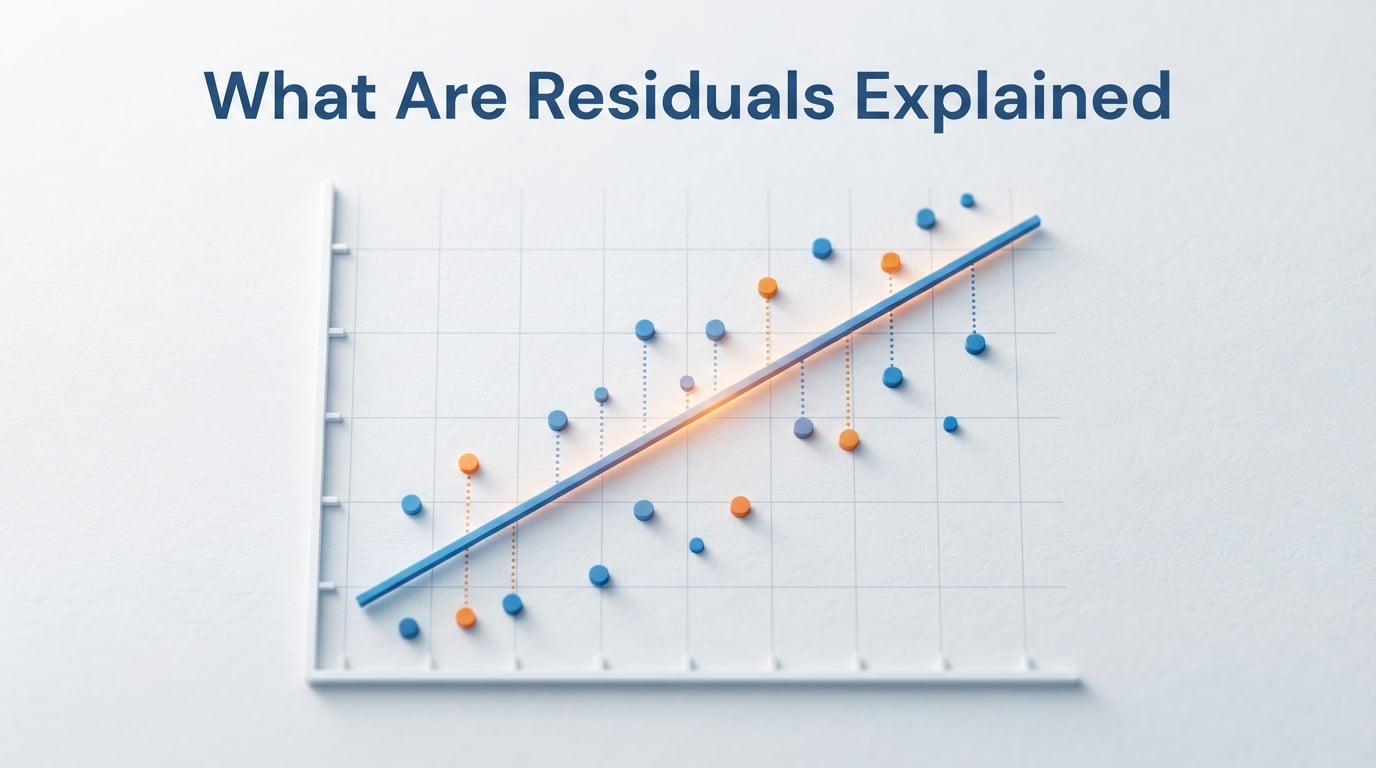
A residual is the vertical distance between an actual data point and the regression line your model drew through your data. In plain English: it’s the mistake your model made on that one point.
Imagine you predicted it would rain 2 inches this month, but only 1.4 inches actually fell. Your prediction was off by 0.6 inches. That 0.6 is the residual for that observation. Simple, right?
Residuals exist because no model is perfect. Real data has noise, randomness, and things your model can’t capture. The residual is how we measure that gap for each individual point.
The word “residual” literally means “what’s left over.” After your model takes its best shot at predicting a value, the residual is what’s left over, the unexplained part.
Every model makes predictions, and every prediction is off by some amount. That amount, observation by observation, is the residual. When you hear statisticians talk about “model fit,” they’re really talking about whether those residuals are small and random or large and systematic.
Residuals for Beginners
If you’ve ever made a budget and ended up spending less than expected, the leftover money is like a residual. Your plan said one thing; reality said another. The difference between your planned and actual numbers is what we’re talking about, just applied to statistics.
Another way to picture it: think of a dartboard. The bullseye is the predicted value, and the dart is the actual value. The distance between the dart and the bullseye is the residual. Darts that land above the bullseye have positive residuals; those below have negative ones.
That’s really all there is to the basic idea. Everything else is just details, formulas, and conventions for how we use this concept.
The Residual Formula Explained
The residual formula is one of the simplest equations in statistics: Residual = Observed − Predicted.
In symbols, statisticians often write this as:
eᵢ = yᵢ − ŷᵢ
Where eᵢ is the residual for the i-th observation, yᵢ is the observed (actual) value, and ŷᵢ is the predicted value from your model. The little “hat” over the y (ŷ) is a convention that means “this is a predicted value.”
If observed is bigger than predicted, the residual is positive (your model under-predicted). If observed is smaller than predicted, the residual is negative (your model over-predicted). When they match exactly, the residual is zero.
The reason we subtract predicted from observed (and not the other way around) is convention. Some textbooks flip it, but the most common practice is Observed − Predicted. Either way, the sign tells you which direction the error went.
What “Observed” and “Predicted” Mean
The observed value is the real data you collected. If you measured someone’s height as 68 inches, that 68 is your observed value. No model involved, just measurement.
The predicted value is what your regression line says it should be, given the input. If your model says a 170-pound person should be about 67 inches tall, then 67 is the predicted value.
The residual for that observation is 68 − 67 = +1. Your model under-predicted by one inch.
Positive, Negative, and Zero Residuals
Every residual falls into one of three buckets, and each one tells you something different about how your model performed on that particular observation.
A positive residual means your model under-predicted. The actual value was higher than what your line said it should be. The point sits above the regression line on a scatter plot.
A negative residual means your model over-predicted. The actual value was lower than expected. The point sits below the regression line.
A zero residual is rare in real data and means your model nailed that prediction exactly. The point lands right on the line.
Quick Visual Guide
- Point above the line = positive residual (model guessed too low)
- Point on the line = zero residual (model nailed it)
- Point below the line = negative residual (model guessed too high)
Picture a scatter plot with a diagonal line cutting through it. Now imagine each dot is connected to the line by a tiny vertical string. That string is the residual, and its direction (up or down) tells you whether your model under- or over-shot.
The length of that string tells you how big the error was. A long string means a big miss; a short string means the model was close.
How to Calculate Residuals Step by Step
Let’s work through a real example. Say we have data on study hours and exam scores for five students, and our linear regression model predicts exam scores from study hours using this equation:
Predicted Score = 50 + 5 × (Study Hours)
This means a student who studied zero hours would be predicted to score 50, and each additional hour of study adds 5 points to the predicted score. Now we’ll calculate the residual for each student.
Step 1: List Your Observed Values
Five students studied for 2, 4, 6, 8, and 10 hours. Their actual exam scores were 65, 75, 78, 88, and 95.
These are your observed values (yᵢ). You can think of these as ground truth, the actual data points you collected.
Step 2: Calculate the Predicted Value for Each
Plug each study hour into the model’s equation:
- Student 1 (2 hours): 50 + 5×2 = 60
- Student 2 (4 hours): 50 + 5×4 = 70
- Student 3 (6 hours): 50 + 5×6 = 80
- Student 4 (8 hours): 50 + 5×8 = 90
- Student 5 (10 hours): 50 + 5×10 = 100
These are your predicted values (ŷᵢ). Each one is what the model “thinks” the score should be, based on study time alone.
Step 3: Subtract Predicted from Observed
Now apply the formula Residual = Observed − Predicted:
- Student 1: 65 − 60 = +5
- Student 2: 75 − 70 = +5
- Student 3: 78 − 80 = −2
- Student 4: 88 − 90 = −2
- Student 5: 95 − 100 = −5
Students 1 and 2 beat the prediction (positive residuals). Students 3, 4, and 5 fell short of what the model expected (negative residuals). That’s the calculation in a nutshell.
What the Numbers Tell Us
Notice that the residuals sum to +1, not zero. In real data with a fitted model, they’d sum to exactly zero. This example uses a simplified model equation that I chose for clarity. With a properly fitted regression line (using ordinary least squares), the residuals would always cancel out.
The takeaway: residuals tell you where the model is right and where it’s wrong, point by point.
Residual Plots: How to Read Them
A residual plot is a graph that puts each residual on the y-axis and the predicted value (or sometimes the input variable) on the x-axis. It’s one of the most useful diagnostic tools in regression analysis.
The reason we use residual plots is that they reveal patterns the original scatter plot hides. When you plot raw data against a regression line, you can see the overall fit. When you plot the residuals, you can see whether the fit was a good idea in the first place, whether the linear model is appropriate, whether the variance is constant, and whether outliers are lurking.
What a Good Residual Plot Looks Like
In a good residual plot, the points look like random noise scattered around zero. There’s no clear shape, no curve, no funnel. Just dots bouncing around the horizontal line at y = 0.
This randomness tells you your model captured the real pattern in the data. Whatever’s left over is just noise, the kind of unpredictable variation you’d expect from real-world measurements.
If you squint and see nothing, that’s good. Empty space with random scatter is what you want.
Warning Signs in Residual Plots
If you see patterns, your model is missing something. Here are the most common red flags.
A U-shape or curved pattern means a linear model was wrong. The residuals bend systematically, which tells you the true relationship is curved. You probably need a polynomial or nonlinear model.
A funnel shape, where residuals spread out as predictions grow larger, is called heteroscedasticity. It means your model’s errors aren’t constant across the range of predictions. This violates a key assumption of ordinary least squares regression.
Any clear trend or slope in residuals means your model has systematic bias. It’s consistently over- or under-predicting in some region of the data.
If a single residual is way bigger than the others, that’s an outlier worth investigating. It might be a typo, a measurement error, or a genuinely unusual case your model can’t explain.
Common Patterns and What They Mean
- Random scatter around zero: model is appropriate, errors are well-behaved
- U-shape or curve: linear model is wrong, consider polynomial regression
- Funnel shape (heteroscedasticity): variance isn’t constant, consider transforming variables
- Trend line in residuals: model is biased, missing an important variable
- One or two extreme points: outliers, investigate before trusting the model
Learning to read these patterns is one of the most valuable skills in data analysis. Once you can spot them, you’ll catch model problems before they cause bad decisions.
Why the Sum of Residuals Equals Zero
One of the most common questions I see on statistics forums is: “Why does the sum of residuals always equal zero?” It’s a great question, and the answer is built into how regression works.
The regression line is calculated using a method called ordinary least squares (OLS), which finds the line that minimizes the sum of squared residuals. As a mathematical consequence of this method, the positive residuals and negative residuals cancel each other out exactly when you add them up.
The mean of all residuals is therefore also zero. That’s not a coincidence; it’s a built-in feature of how the regression line is positioned. The line passes through the average point of your data, which forces the residuals to balance out above and below.
This property is also why we square residuals when we evaluate model fit. Squared values are always positive, so the sum of squared residuals doesn’t cancel out. That gives us a meaningful measure of total error.
Residuals vs Errors: What’s the Difference?
People often use “residual” and “error” interchangeably, but in formal statistics they mean different things. The distinction matters more than you might think.
An error is the difference between the observed value and the true (but unknown) population value. The true value is what you’d get with infinite data and a perfect measurement. Errors are theoretical; we can never observe them directly.
A residual is the difference between the observed value and the predicted value from your sample model. Since your model is estimated from a finite sample, residuals are observable and based on real numbers.
In practice, we treat residuals as estimates of errors. We can’t measure the error directly, so we use the residual as our best guess. When statisticians check “whether errors are normally distributed,” they’re really checking residuals.
The distinction matters because residuals can be smaller than errors in a misleading way. Your model is built to fit your specific sample, so residuals tend to look better than the true errors would. This is one reason statisticians use techniques like cross-validation.
Residuals and Model Fit: Connection to R-Squared
Residuals connect directly to one of the most popular measures of model quality: R-squared. If you’ve ever been asked “how good is your model?” you’ve probably encountered R-squared.
R-squared measures the proportion of variation in your data that the model explains. It’s calculated by comparing the sum of squared residuals to the total variation in the data. Smaller residuals mean a higher R-squared, which means a better fit.
An R-squared of 1.0 means residuals are all zero, the model explains everything perfectly. An R-squared of 0 means the model is no better than just guessing the average. Most real models fall somewhere in between.
So when you look at residuals, you’re really looking at the raw material that R-squared summarizes in a single number. They’re two views of the same underlying story.
Residuals in Everyday Contexts: Other Meanings
The word “residuals” shows up in places that have nothing to do with statistics. If you’ve searched for “what are residuals explained” and seen results about music or movies, you’re not crazy.
In the entertainment industry, residuals are ongoing payments made to creators (actors, writers, musicians) whenever their work is replayed. For example, when a song streams on a platform or a TV show airs in syndication, the performers get a small residual payment based on their original contract.
This is why you might find queries like “what are Chris Brown residuals” when looking up the term. Fans sometimes research how much artists earn from streaming royalties, which are technically residuals in the entertainment sense.
The two meanings share a name because both describe “what’s left over” from the original transaction. In statistics, it’s the leftover unexplained variation. In entertainment, it’s the leftover money that keeps flowing after the original work is done.
Same word, totally different worlds.
Frequently Asked Questions About Residuals
What are residuals in simple terms?
A residual is the difference between an actual data point and the value your model predicted for it. If your model said sales would be 100 but actual sales were 110, the residual is +10.
Should residuals be high or low?
Lower residuals mean a better-fitting model. Large residuals (in absolute value) suggest the model is missing something. What counts as ‘low’ depends on the scale of your data.
How do you find a residual?
Use the formula Residual = Observed minus Predicted. Take the actual data point, subtract what your model predicted for it, and you have the residual. Positive means under-prediction, negative means over-prediction.
What are residuals in a relationship?
In everyday speech, ‘residual’ sometimes means leftover emotional or practical baggage from a past relationship. In statistics, it means leftover unexplained variation in your model. Same word, different context.
What is the meaning of Chris Brown’s residuals?
This refers to entertainment-industry residuals, which are ongoing royalty payments artists receive when their music is streamed, played on radio, or used in media. They’re separate from the statistical meaning of residuals.
Should residuals be normally distributed?
For many statistical tests and confidence intervals to be valid, residuals should be approximately normally distributed. You can check this with a histogram or a Q-Q plot of your residuals. Small deviations are usually fine.
What is a good residual plot?
A good residual plot shows random scatter around zero with no visible pattern. If you see curves, funnels, or trends, your model has a problem that needs fixing.
Final Thoughts on What Residuals Tell You
So, what are residuals really? They’re the scorecard for your model’s predictions. Each one tells you how far off your model was for a specific data point, and together they reveal whether your model is doing its job or hiding problems.
If you’ve made it this far, you now know the residual formula, how to calculate residuals by hand, how to read a residual plot, how residuals relate to errors and R-squared, and what residuals mean in contexts outside statistics. The next step is to grab a small dataset, fit a simple linear regression in Excel or Google Sheets, and check the residuals yourself. Seeing the pattern in real data is what cements the concept.
If you found this guide helpful, share it with anyone wrestling with regression for the first time. Once residuals click, statistics gets a lot less intimidating.